Reflection Reflection 官方 Official 社区 showcase Community showcase

Beam:Reflection 的 501B 开源权重模型(还不能下载) Beam: Reflection’s 501B open-weight model (not downloadable yet)

Beam: Reflection’s 501B open-weight model (not downloadable yet)

Beam 是 Reflection 在 2026 年 10 月 5 日公开的开源权重模型,给要写代码、做推理、让编程助手干活的人用。它是稀疏混合专家:参数一共 5010 亿,每次真正计算时只用其中 230 亿。现在还不能下载。官网写它还在做最后一轮安全测试(专门找它会不会被带去干不该干的事),眼下只能到平台页登记提前试用;权重、技术报告、模型卡和给开发者的配套,都说这个月晚些时候才放,并打算用 Apache 2.0。页面表格里的分数是厂商自己报的,这里没有复跑。 Beam is Reflection’s open-weight model, announced on 5 October 2026, for people who write code, reason through problems, or hand work to a coding agent. It is a sparse mixture-of-experts model: 501 billion parameters in total, with 23 billion active on each step. It is not downloadable yet. The site says it is still in final safety testing (checking whether it can be talked into doing something it should not), and that early access is a signup only. Weights, the technical report, the model card, and the developer extras are promised later this month, under Apache 2.0. The scores on the page are the vendor’s own numbers and were not re-run here.
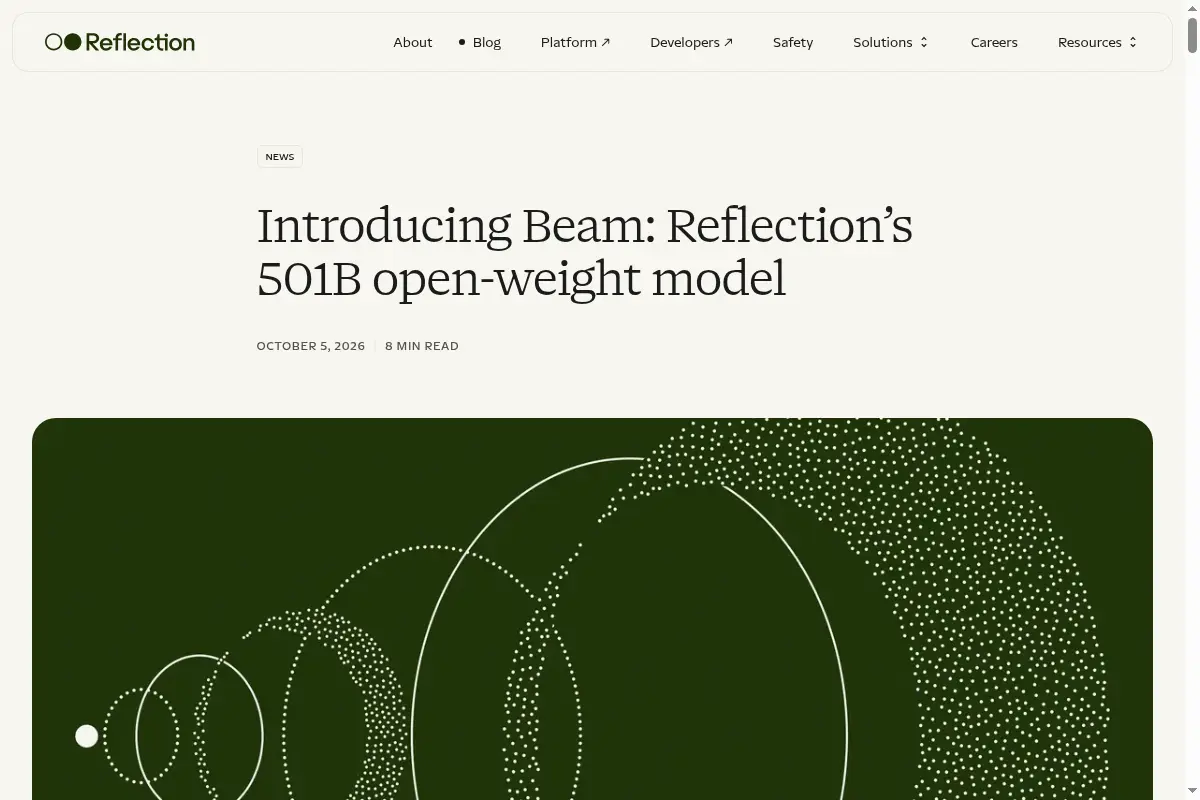
预览:Chrome 实拍 reflection.ai/blog/introducing-beam 首屏 Preview: Chrome capture of reflection.ai/blog/introducing-beam above the fold

来源Sources

为什么推荐Why we recommend it 博文写明:仍在最终 red-teaming(安全对抗测试)和评测中;权重、技术报告、模型卡和 developer artifacts 这个月晚些时候才发布,许可写的是 Apache 2.0。所以现在不能当已可下载的开源模型。表格数字、3–4 倍推理计算量、23.8 万亿 token、GPU 数量、1 亿次尝试、256K / 1M 上下文都是厂商自述,本库未复跑、未下权重。与 gemini-4-argon、gpt-6-astra、claude-opus-5-5 互链。 The static HTML shows no weight download, and this library did not sign up. The post says final red-teaming and evaluations are still underway, and that the weights, technical report, model card, and developer artifacts come later this month under Apache 2.0. It is not a downloadable open model today. The table, the 3–4× inference-compute claim, 23.8 trillion tokens, the GPU counts, the 100 million rollouts, and the 256K / 1M context figures are vendor claims — not re-run here, weights not downloaded. Featured, unrated. Cross-linked with gemini-4-argon, gpt-6-astra, and claude-opus-5-5.

核验记录:来源、抓取与截图说明Verification log: sources, checks, and captures

收录理由:HN item 49969183(标题 Beam: Reflection's 501B open-weight model,提交者 Philpax,2026-10-05T19:16:35.000Z / 约 2026-10-06 03:16 CST)。撰写时 HN 页面与 Algolia 都是 478pts。官博 https://reflection.ai/blog/introducing-beam 撰写时 HTTP 200,页内日期 October 5, 2026,8 min read。提前试用链接指向 https://platform.reflection.ai/ ,撰写时 HTTP 200,但是一个要脚本才能画出的平台页;静态 HTML 里看不到权重下载,本库没有登记账号。Artificial Analysis 的 https://artificialanalysis.ai/models/beam 与 https://artificialanalysis.ai/models/reflection-beam 撰写时均为 HTTP 404,不编第三方榜链接。预览为 Chrome 实拍官博首屏裁 3:2 WebP。精选,不打星。Why: HN item 49969183 (title Beam: Reflection's 501B open-weight model, submitter Philpax, 2026-10-05T19:16:35.000Z / about 03:16 CST on 2026-10-06). At write time the HN page and Algolia both showed 478pts. The blog https://reflection.ai/blog/introducing-beam returned HTTP 200; the page is dated October 5, 2026, 8 min read. Early access points at https://platform.reflection.ai/, which returned HTTP 200 but is a script-drawn platform page. Artificial Analysis URLs https://artificialanalysis.ai/models/beam and https://artificialanalysis.ai/models/reflection-beam both returned HTTP 404, so no third-party board link is invented. Preview is a Chrome capture of the blog above the fold, cropped to 3:2 WebP.

要点(官方称 / 社区称)Highlights (vendor / community claims)

  • 官方称:稀疏混合专家,总参数 5010 亿、每次启用 230 亿,面向写代码、推理和让助手干活。模型本身只处理文字;图片或别的材料要先变成文字它才能用。现在还不能下载。博文写正在做最后的安全测试,提前试用只是登记;权重、技术报告、模型卡和开发者配套「这个月晚些时候」放出,许可打算用 Apache 2.0。 Vendor claim: a sparse mixture-of-experts model, 501 billion parameters total and 23 billion active, built for coding, reasoning, and agent work. The model itself is text-only; images or other material have to be turned into text first. It is not downloadable yet. The post says final safety testing is still underway and early access is a signup. Weights, the technical report, the model card, and developer extras are promised later this month, under Apache 2.0.
  • 官方表格(本库未复跑,NR 表示对方没公布):Beam 一列里 DeepSWE v1.1 为 44.4,Terminal Bench v2.1 为 80.1,SWE Bench Pro v1 为 65.5,SWEBench Verified 为 80.9,不用工具的 HLE 为 36.2,GPQA Diamond 为 90.5。正文另称:在更难的推理测试上,分数和 GLM-5.2 差不多,推理计算量大约少 3 到 4 倍。这是厂商比较,不是本库测出来的名次。 Vendor table (not re-run here; NR means the other lab did not publish a score). In the Beam column: DeepSWE v1.1 44.4, Terminal Bench v2.1 80.1, SWE Bench Pro v1 65.5, SWEBench Verified 80.9, HLE with no tools 36.2, GPQA Diamond 90.5. The prose also says that on harder reasoning tests the scores are comparable to GLM-5.2 at about 3–4× less inference compute. That comparison is the vendor’s, not a ranking produced here.
  • 官方称:预训练用了 23.8 万亿 token(文本切成的小段),在 6144 张 NVIDIA GB300 NVL72 上不到四周跑完。强化学习用 1.05 万张 NVIDIA GB300,四周里产生超过 1 亿次尝试,单次上下文最长 256K token;文中写中期训练把可用上下文拉到 100 万 token。这些都是厂商自述,本库没有复现训练。 Vendor claim: pretraining used 23.8 trillion tokens and finished in under four weeks on 6,144 NVIDIA GB300 NVL72 GPUs. Reinforcement learning used 10,500 NVIDIA GB300 GPUs, produced more than 100 million rollouts over four weeks, and allowed up to 256K tokens of context; the post says midtraining extends usable context to 1 million tokens. All of that is the vendor’s account. This library did not reproduce the training.

同板相关Related on this board

同一看板上互相关联的卡:社区 demo 指回它跑的模型,模型指向值得看的 demo。Cards linked on this board: a community demo points back to the model it ran on; the model points to demos worth a look.